

Professional Machine Learning Engineer Free Sample Questions

Description

Covers low-code AI solutions with BigQuery ML and AutoML, data exploration and experiment tracking, building and training models, serving and scaling them, and monitoring AI solutions.

20 free sample questions241 in the full practice test Other version: GCP-PMLE-Ext(135)

Try simulator

GCP-PMLE Sample Questions

  1. Question 1

    You are an ML engineer at a large grocery retailer with stores in multiple regions. You have been asked to create an inventory prediction model. Your model’s features include region, location, historical demand, and seasonal popularity. You want the algorithm to learn from new inventory data on a daily basis. Which algorithms should you use to build the model?

    Answer and explanation

    Correct answer: C

    Predicting inventory from region, location, historical demand and seasonal popularity is a supervised forecasting problem over time-ordered data. Recurrent neural networks (for example, LSTMs) model temporal dependencies such as seasonality and trends, and the model can be retrained daily on the newest inventory data. Reinforcement learning learns a policy for taking actions from reward signals rather than predicting a labeled quantity, classification predicts discrete classes rather than a demand quantity, and CNNs are designed for spatial (image-like) data.
  2. Question 2

    You have trained a deep neural network model on Google Cloud. The model has low loss on the training data, but is performing worse on the validation data. You want the model to be resilient to overfitting. Which strategy should you use when retraining the model?

    Answer and explanation

    Correct answer: C

    Low loss on the training data with worse performance on the validation data means that the model is overfitting. L2 regularization and dropout are the standard ways to reduce overfitting, and their best values are found by experiment. So run a hyperparameter tuning job on Agent Platform (formerly Vertex AI) that searches over the L2 regularization and dropout parameters. Choosing one fixed dropout or L2 value and reducing the learning rate is guesswork, and the learning rate isn't a regularization setting. Tuning only the learning rate and doubling the number of neurons adds model capacity, which makes overfitting worse.

  3. Question 3

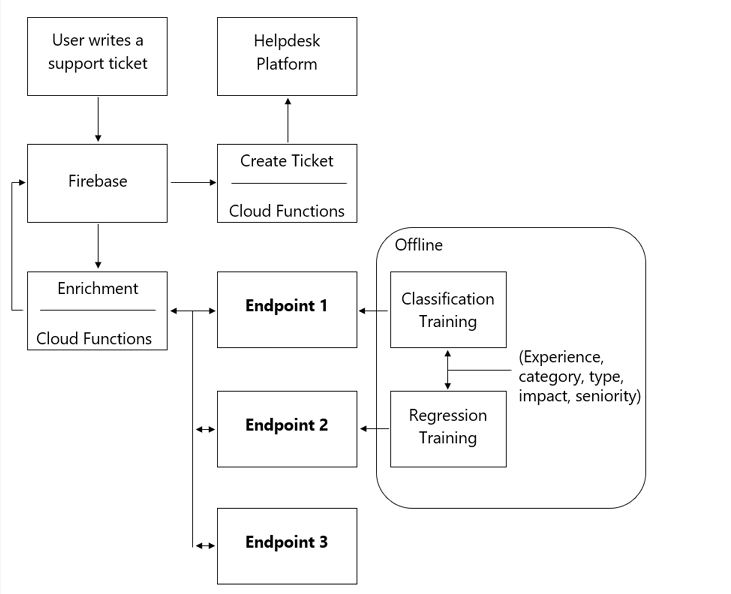
    You are designing an architecture with a serverless ML system to enrich customer support tickets with informative metadata before they are routed to a support agent. You need a set of models to predict ticket priority, predict ticket resolution time, and perform sentiment analysis to help agents make strategic decisions when they process support requests. Tickets are not expected to have any domain-specific terms or jargon.

    In the proposed architecture, new tickets trigger enrichment Cloud Run functions that call three endpoints: endpoint 1 predicts ticket priority, endpoint 2 predicts ticket resolution time, and endpoint 3 performs sentiment analysis. The enriched tickets are then routed to support agents.

    Which endpoints should the enrichment functions call?

    Question 3 image
    Answer and explanation

    Correct answer: C

    Ticket priority and resolution time are organization-specific predictions that require custom models trained on your own ticket history, so they are served from Gemini Enterprise Agent Platform (formerly Vertex AI) endpoints. Sentiment analysis of general-language text with no domain-specific jargon is exactly what the pre-trained Cloud Natural Language API provides, so no custom sentiment model needs to be trained or maintained. Vision models do not apply to text tickets.

  4. Question 4

    You work for a credit card company and have been asked to create a custom fraud detection model based on historical data using AutoML on Gemini Enterprise Agent Platform (formerly Vertex AI). You need to prioritize detection of fraudulent transactions while minimizing false positives. Which optimization objective should you use when training the model?

    Answer and explanation

    Correct answer: A

    Fraud is the rare (less common) class. For AutoML tabular classification, the AUC PR objective "maximize the area under the precision-recall curve" optimizes results for inferences for the less common class, balancing precision (few false positives) and recall (catching fraud). AUC ROC is the binary default and weighs both classes, log loss optimizes probability calibration, and precision at a fixed recall of 0.50 would miss half of the fraud.

  5. Question 5

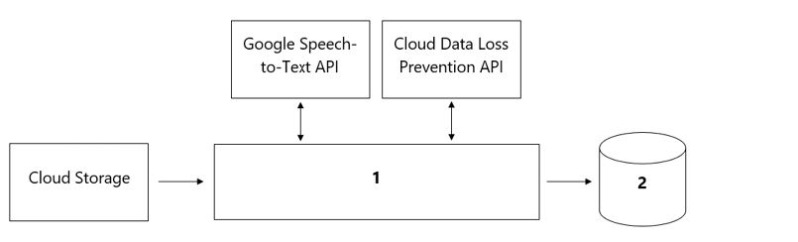
    Your organization’s call center has asked you to develop a model that analyzes customer sentiments in each call. The call center receives over one million calls daily, and data is stored in Cloud Storage. The data collected must not leave the region in which the call originated, and no Personally Identifiable Information (PII) can be stored or analyzed. The data science team has a third-party tool for visualization and access which requires a SQL ANSI-2011 compliant interface. You need to select components for data processing (component 1) and for analytics (component 2). How should the data pipeline be designed?

    Question 5 image
    Answer and explanation

    Correct answer: A

    Dataflow can process more than a million calls per day at scale in the originating region and can call Sensitive Data Protection (DLP) to de-identify PII before storage. BigQuery provides regional datasets and GoogleSQL, an ANSI-compliant SQL dialect, for the third-party visualization tool. Pub/Sub is messaging rather than processing, Datastore has no ANSI SQL interface, and Cloud SQL and Cloud Run functions are not designed for analytics at this scale.

  6. Question 6

    You are developing ML models with Gemini Enterprise Agent Platform (formerly Vertex AI) for image segmentation on CT scans. You frequently update your model architectures based on the newest available research papers, and have to rerun training on the same dataset to benchmark their performance. You want to minimize computation costs and manual intervention while having version control for your code. What should you do?

    Answer and explanation

    Correct answer: C

    A Cloud Build trigger connected to your Git repository (for example, GitHub) starts a build only when new code is pushed, so retraining runs automatically (no manual intervention), only when the architecture actually changes (minimal compute cost), and the code is version-controlled in Git. Submitting jobs manually with gcloud requires intervention, Cloud Storage is not version control, and a daily Composer sensor adds cost and polling overhead.

  7. Question 7

    You work for an advertising company and want to understand the effectiveness of your company’s latest advertising campaign. You have streamed 500 MB of campaign data into BigQuery. You want to query the table, and then manipulate the results of that query with a pandas dataframe in a Gemini Enterprise Agent Platform Workbench instance (formerly Vertex AI Workbench). What should you do?

    Answer and explanation

    Correct answer: D

    In an Agent Platform Workbench instance the BigQuery client library is preinstalled, and the %%bigquery magic runs the SQL query, converts the results to a pandas DataFrame and can save it to a variable in one step (using the BigQuery Storage API for fast downloads). Exporting to CSV via Drive, local download or Cloud Storage adds unnecessary manual steps.

  8. Question 8

    You are developing a Kubeflow Pipelines (KFP) pipeline that runs on Gemini Enterprise Agent Platform Pipelines (formerly Vertex AI Pipelines). The first step in the pipeline is to issue a query against BigQuery. You plan to use the results of that query as the input to the next step in your pipeline. You want to achieve this in the easiest way possible. What should you do?

    Answer and explanation

    Correct answer: B

    Google Cloud Pipeline Components provide a prebuilt BigqueryQueryJobOp that launches a BigQuery query job, waits for it to finish and exposes the result as a pipeline artifact for downstream steps. Reusing a prebuilt component is the easiest option; writing your own script or custom component adds code to build and maintain, and running the query manually in the console is not part of the automated pipeline.

  9. Question 9

    You are building a model to predict daily temperatures. You split the data randomly and then transformed the training and test datasets. Temperature data for model training is uploaded hourly. During testing, your model performed with 97% accuracy; however, after deploying to production, the model’s accuracy dropped to 66%. How can you make your production model more accurate?

    Answer and explanation

    Correct answer: B

    Temperature readings are a time series. Readings an hour apart are highly correlated, so a random split puts near-copies of the test-period data into the training data. This data leakage made the test accuracy (97%) look much better than the real accuracy in production (66%). Google's guidance is to use a chronological split for time-series tasks. It also says to compute transformation statistics (for normalization or bucketizing) from the training split only and apply them to the validation and test splits. Applying transformations before splitting is itself a source of leakage. Adding more test data, or normalizing the training and test data as separate steps, doesn't remove the leakage that the random split causes.

  10. Question 10

    You need to train a computer vision model that predicts the type of government ID present in a given image using a GPU-powered virtual machine on Compute Engine. You use the following parameters:

    • Optimizer: SGD
    • Image shape = 224*224
    • Batch size = 64
    • Epochs = 10
    • Verbose = 2

    During training you encounter the following error: ResourceExhaustedError: Out Of Memory (OOM) when allocating tensor. What should you do?

    Answer and explanation

    Correct answer: C

    A ResourceExhaustedError (OOM) means the tensors for one training step do not fit in GPU memory. Activation memory scales with the batch size, so reducing the batch size is the standard fix that keeps the model and input resolution unchanged. Changing the optimizer or learning rate does not materially change memory use, and reducing the image shape would change the model input and can hurt accuracy.

Register free for 10 more questions

Or unlock all 241 GCP-PMLE questions with explanations, timed mode and flashcards.